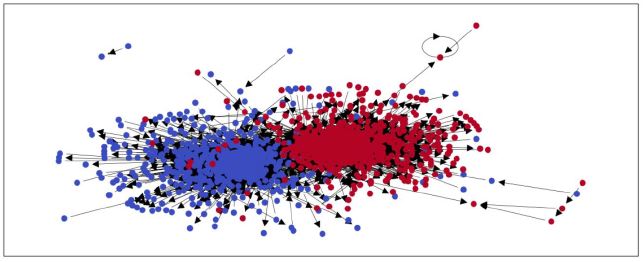
The goal of this project is to classify political blogs as either liberal or conservative using the Polblogs dataset. The dataset used is the one recorded and analysed in this paper proposed in 2005, which contains a collection of the political blogs that were most active in 2004 in the run-up to the US presidential election. This dataset not only includes metadata about individual blogs but also captures the hyperlinks between them, forming a graph structure that reflects the networked nature of political discourse. 📬 Key Features
- Text embedding generation The Polblogs dataset is processed with BERT to obtain text embeddings in order to feed the GCN
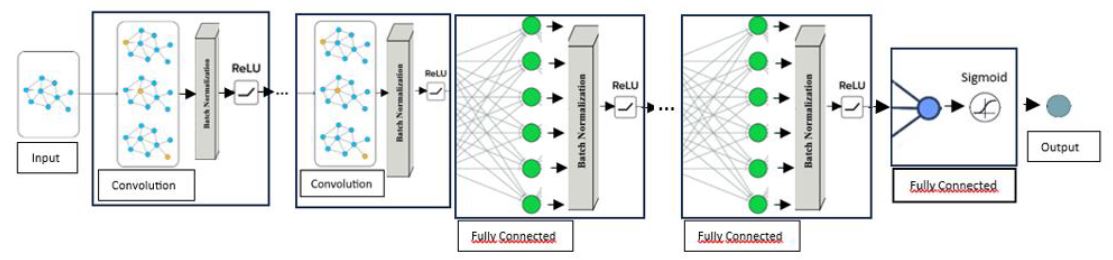
- New architecture proposed A novel architecture is introduced to leverage GCN and adapt them to this dataset
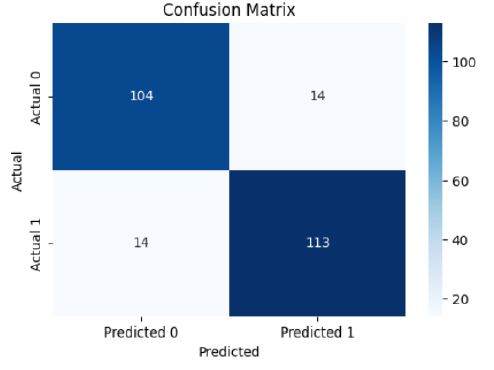
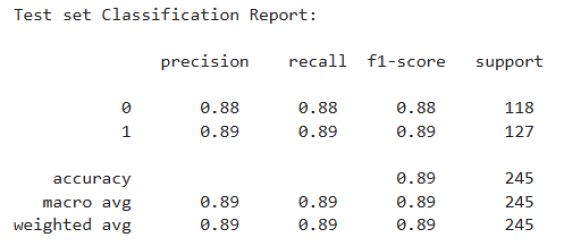
- Metric evaluation on test set After training the model, evaluation metrics were computed on the train set. Here are showed results.
📄 License
This project is distributed under the Apache 2.0 License For more details, visit the Github repository. 
 Google Scholar